Interpreting the results
The following table shows attribute importance based on average impurity decrease (and number of nodes using that attribute). Only attributes with an average impurity decrease ≥ 50% are shown below. These values were generated by Weka. The table illustrates that key, mode, energy, and danceability are the most informative attributes for classifying genre. The t and p attributes (i.e. t2) represent different measures of timbre and pitch.
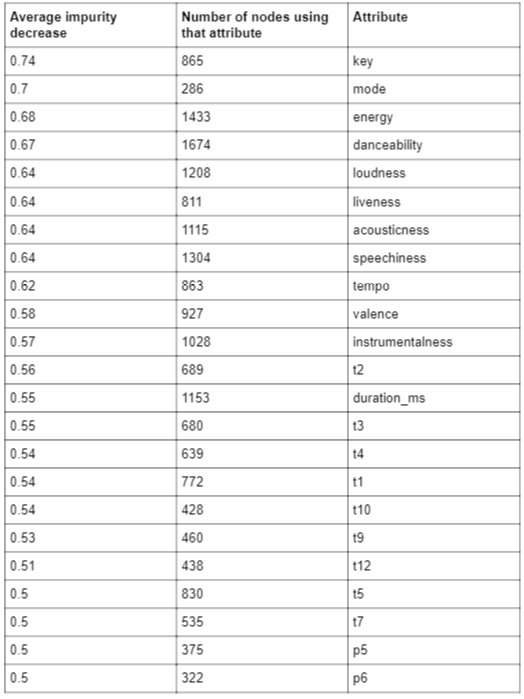
Attribute importance by the number of nodes that ues each attribute in our model